Connect people with the world,
so they look forward, not down.
Meta's mission was building the future of human connection. We needed compelling use cases to find product-market fit on display glasses.
ROLEI led the end-to-end multimodal AI design leveraging photo input and OCR to help people understand and take actions on what they see, including standardizing the human-AI interaction model and gesture vocabulary, contributing to design system, and creative direction for onboarding, education, and commercial artwork.
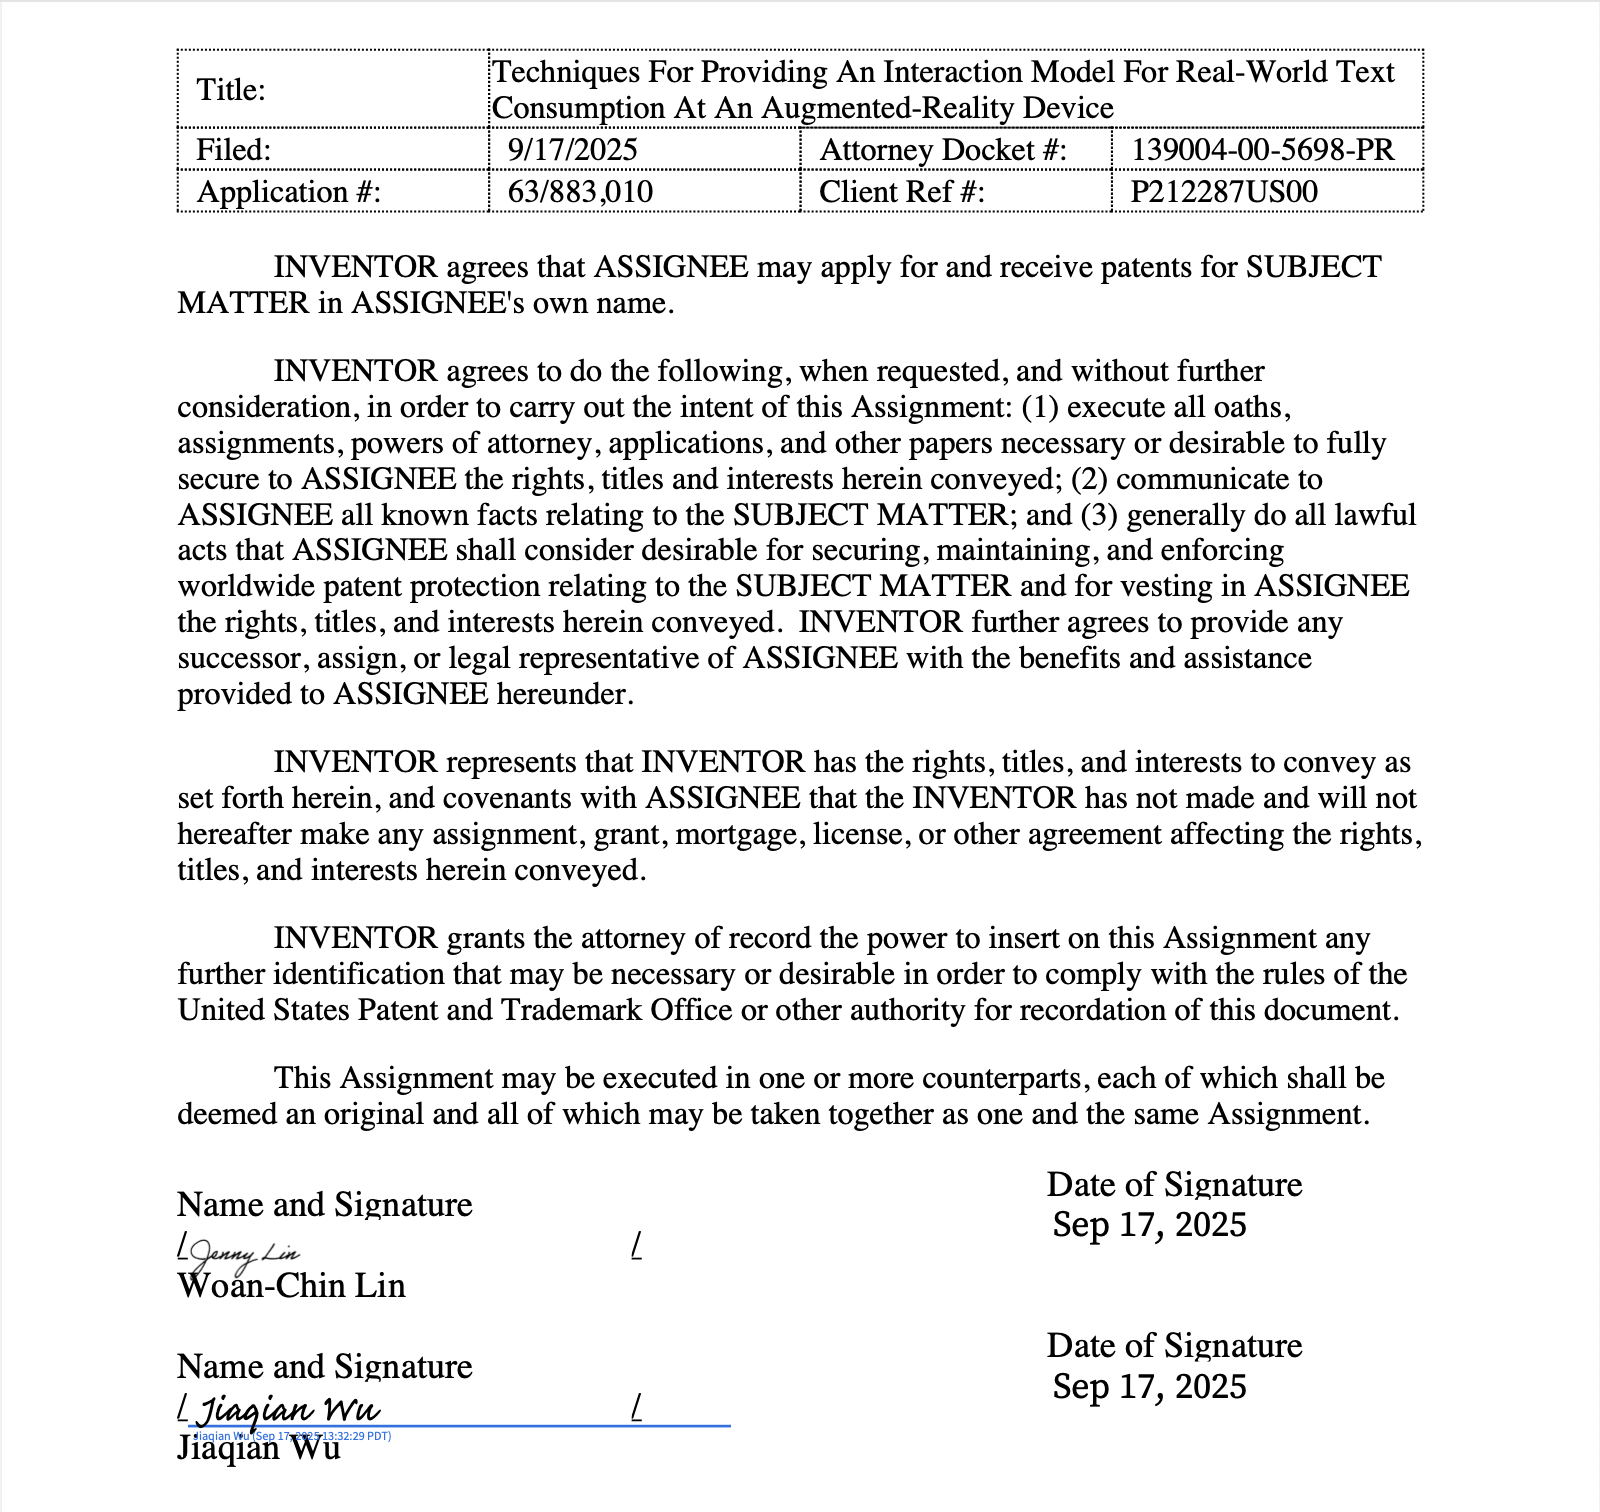
OUTCOMELaunched at Meta Connect 2025. The interaction model my engineer and I designed was filed as a patent, with me as first inventor.
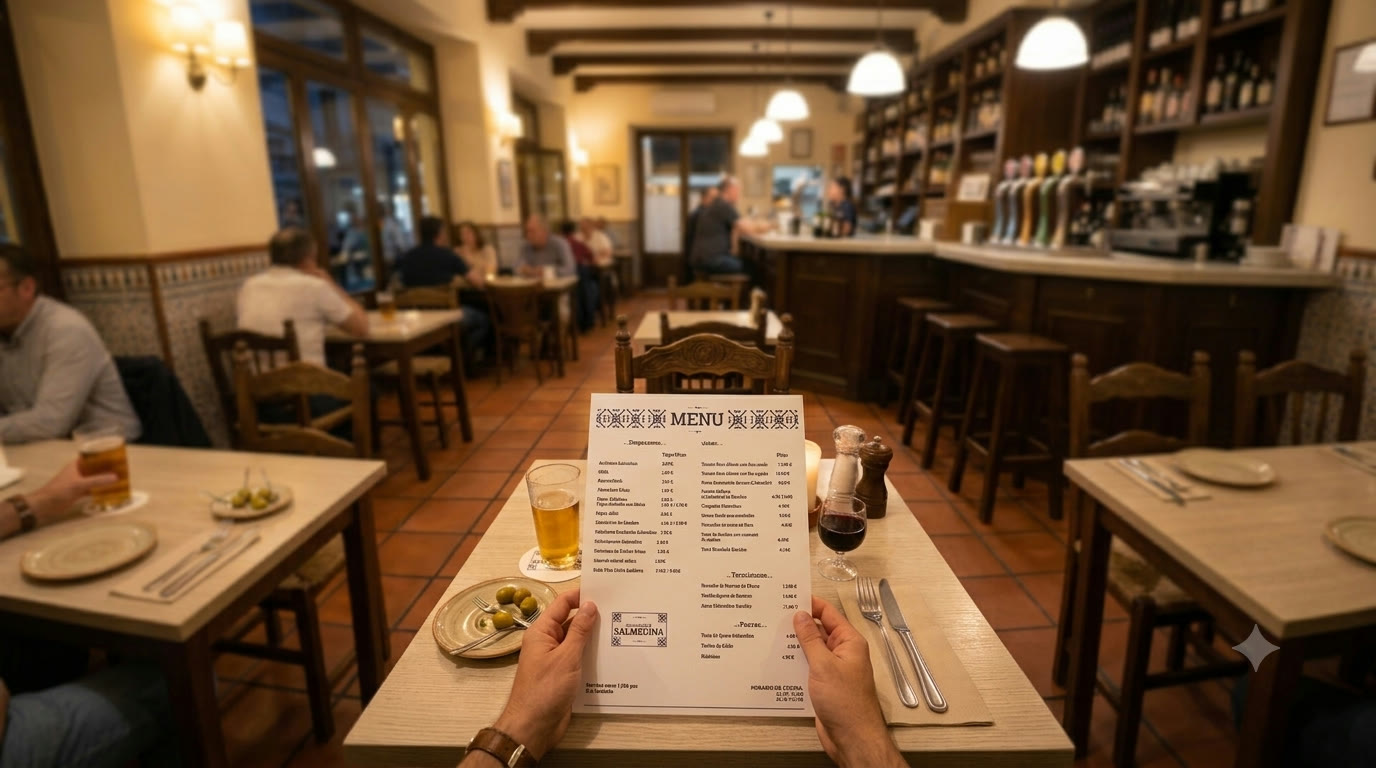
A restaurant abroad. A menu you can't read.
How can wearers consume translations on a transparent display the size of a postage stamp?
If the wearer can't discover the gesture, can't navigate, and can't read the translation — the AI feels broken regardless of whether the translation model is accurate.
Consumer
Discovery
Wearers didn't know zoom and pan were possible on the 600 × 600px display.
Gesture friction
Captouch swipe to zoom was easily mistaken as taps. Head-IMU panning felt jittery.
Legibility
The additive display, contrast, and image resolution can make it hard to read texts.
Technical
Image resolution ↔ latency
Sharper text on the 600 × 600px display needs higher-resolution renders and deeper zoom — heavier processing, slower response.
Natural invocation
Corresponding visual response templates only fired on rigid commands — wearers had to remember exact trigger phrases for the AI to show rich visual responses.
What you see ≠ what you hear
1 OCR input feeds 2 separate models. The rendered translation includes over-detected noise the LLM's audio response cuts — and even on clean input, 2 models means 2 different wordings.
System understanding ≠ human understanding
OCR groups real-world text by adjacency — orientation, line breaks, and layout work against it.
A translation you can
read, move through, and act on —
with nothing to touch.
Every design decision held to 3 principles: intuitive, easy, quick.
Result format
How might we show the translated result on the display and in the AI's audio response — what's the relationship between the two?
Navigation
How might we enable wearers to move through the translated content — with no direct-manipulation surface like a touchscreen?
Follow-up actions
How might we offer the right actions once the translation lands to help wearers reach their goal?
The devil is in the details.
Understanding was never the goal —
acting on it was.
A translation is only useful if you can map it back to the world in front of you. I made the call on intuition and competitor analysis, we built it, then validated with UXR.
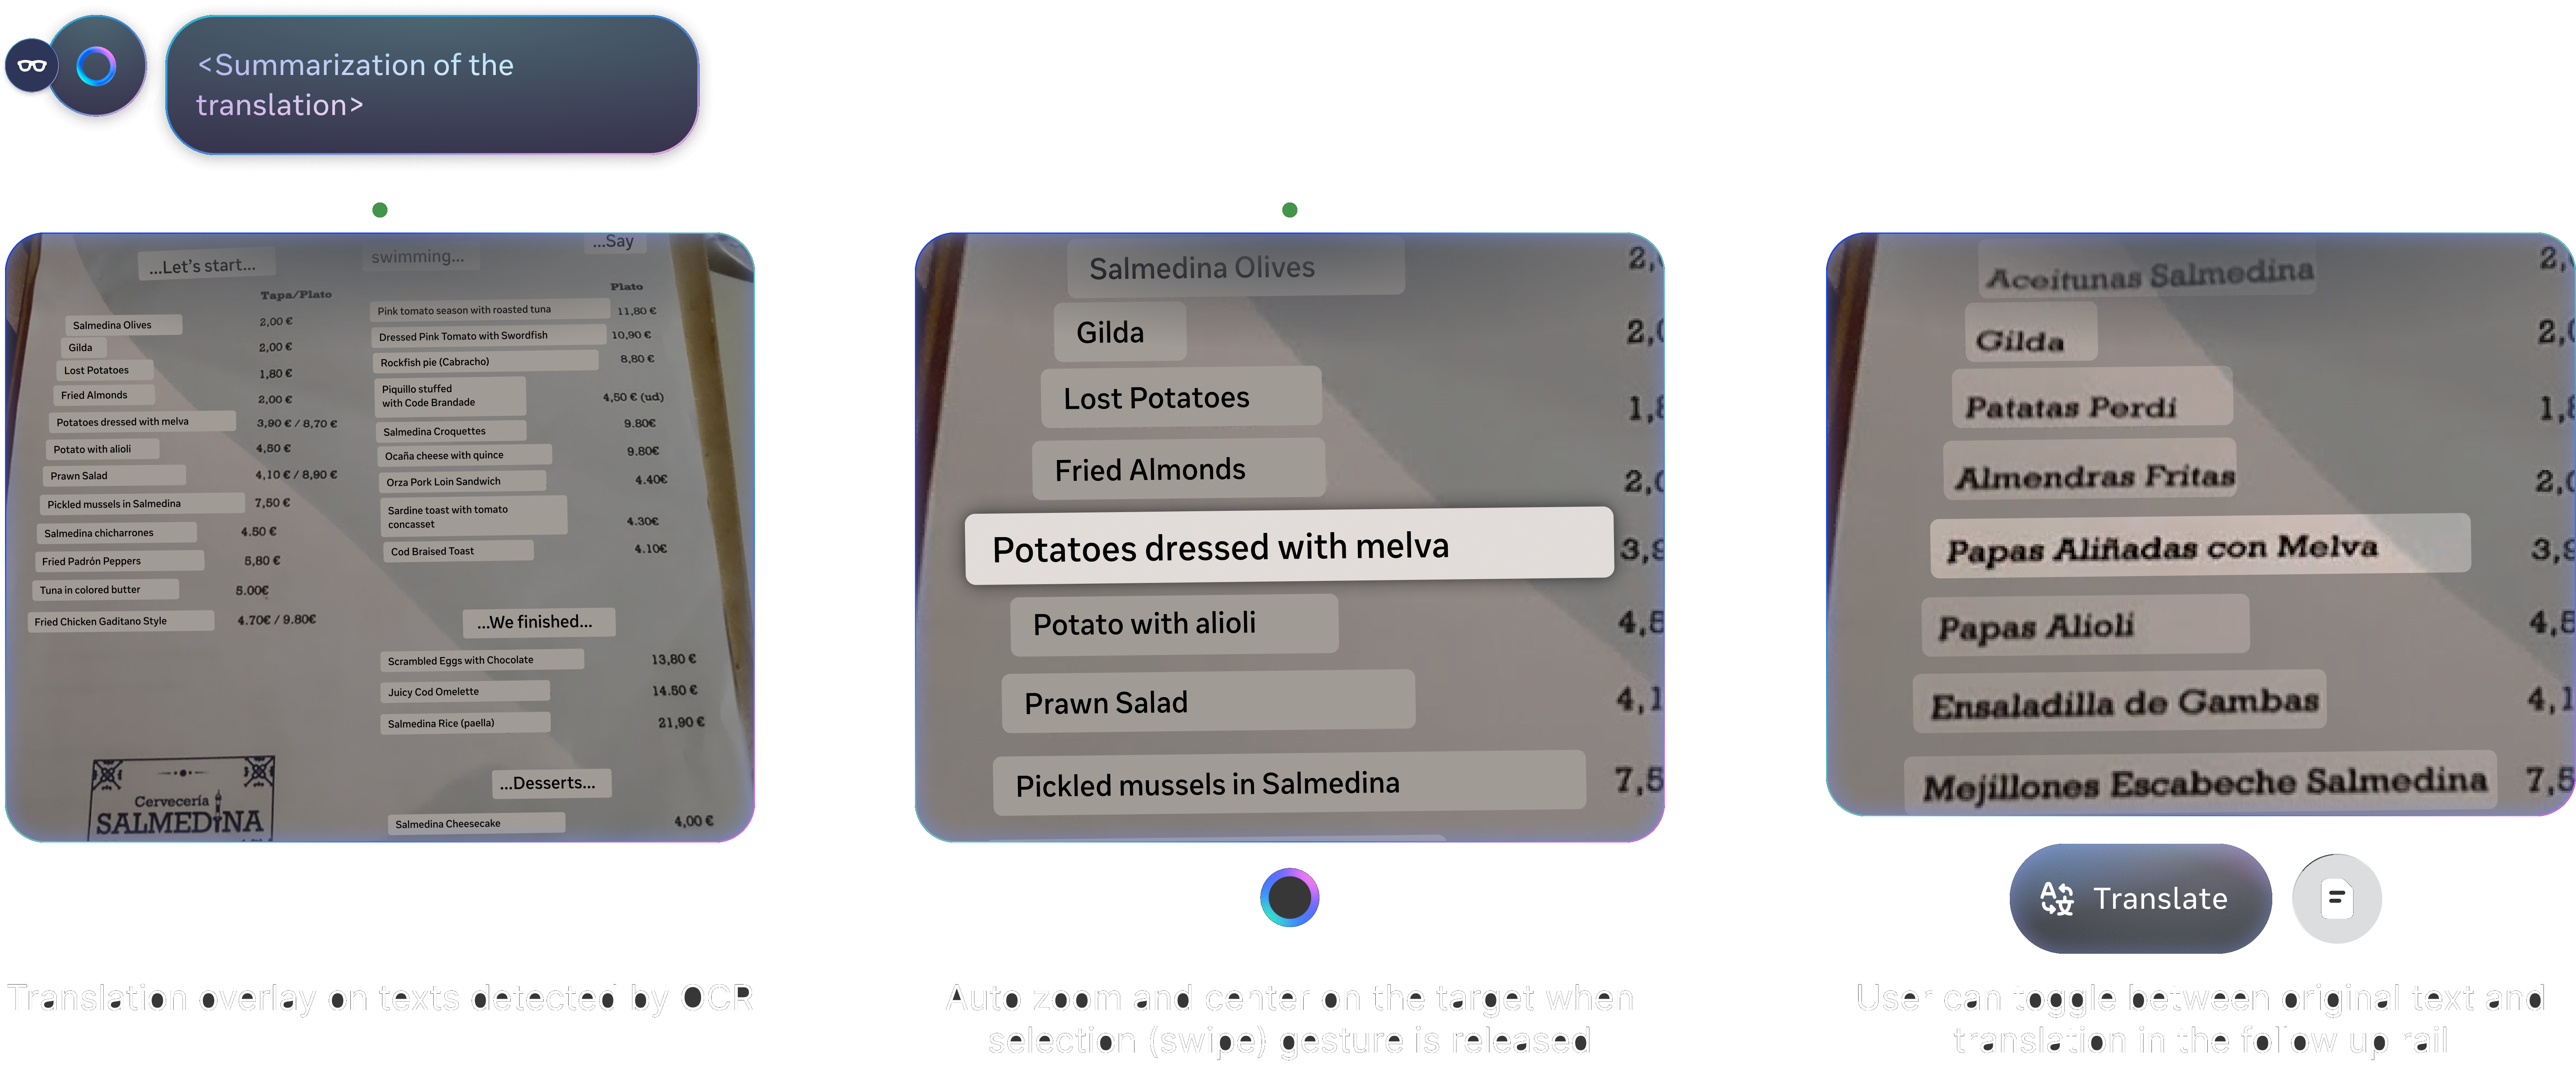
Two ways to put a translation on a display you can’t touch.
I took the one that keeps your eyes in one place.
- Can transfer attention to the display entirely, with no extra eye movement to scan and compare between capture preview and translation
- Can’t scale to include image
- Might be challenging to read depending on the color of the documents and the background environment users are in
Machine picks by proximity;
human follows a path.
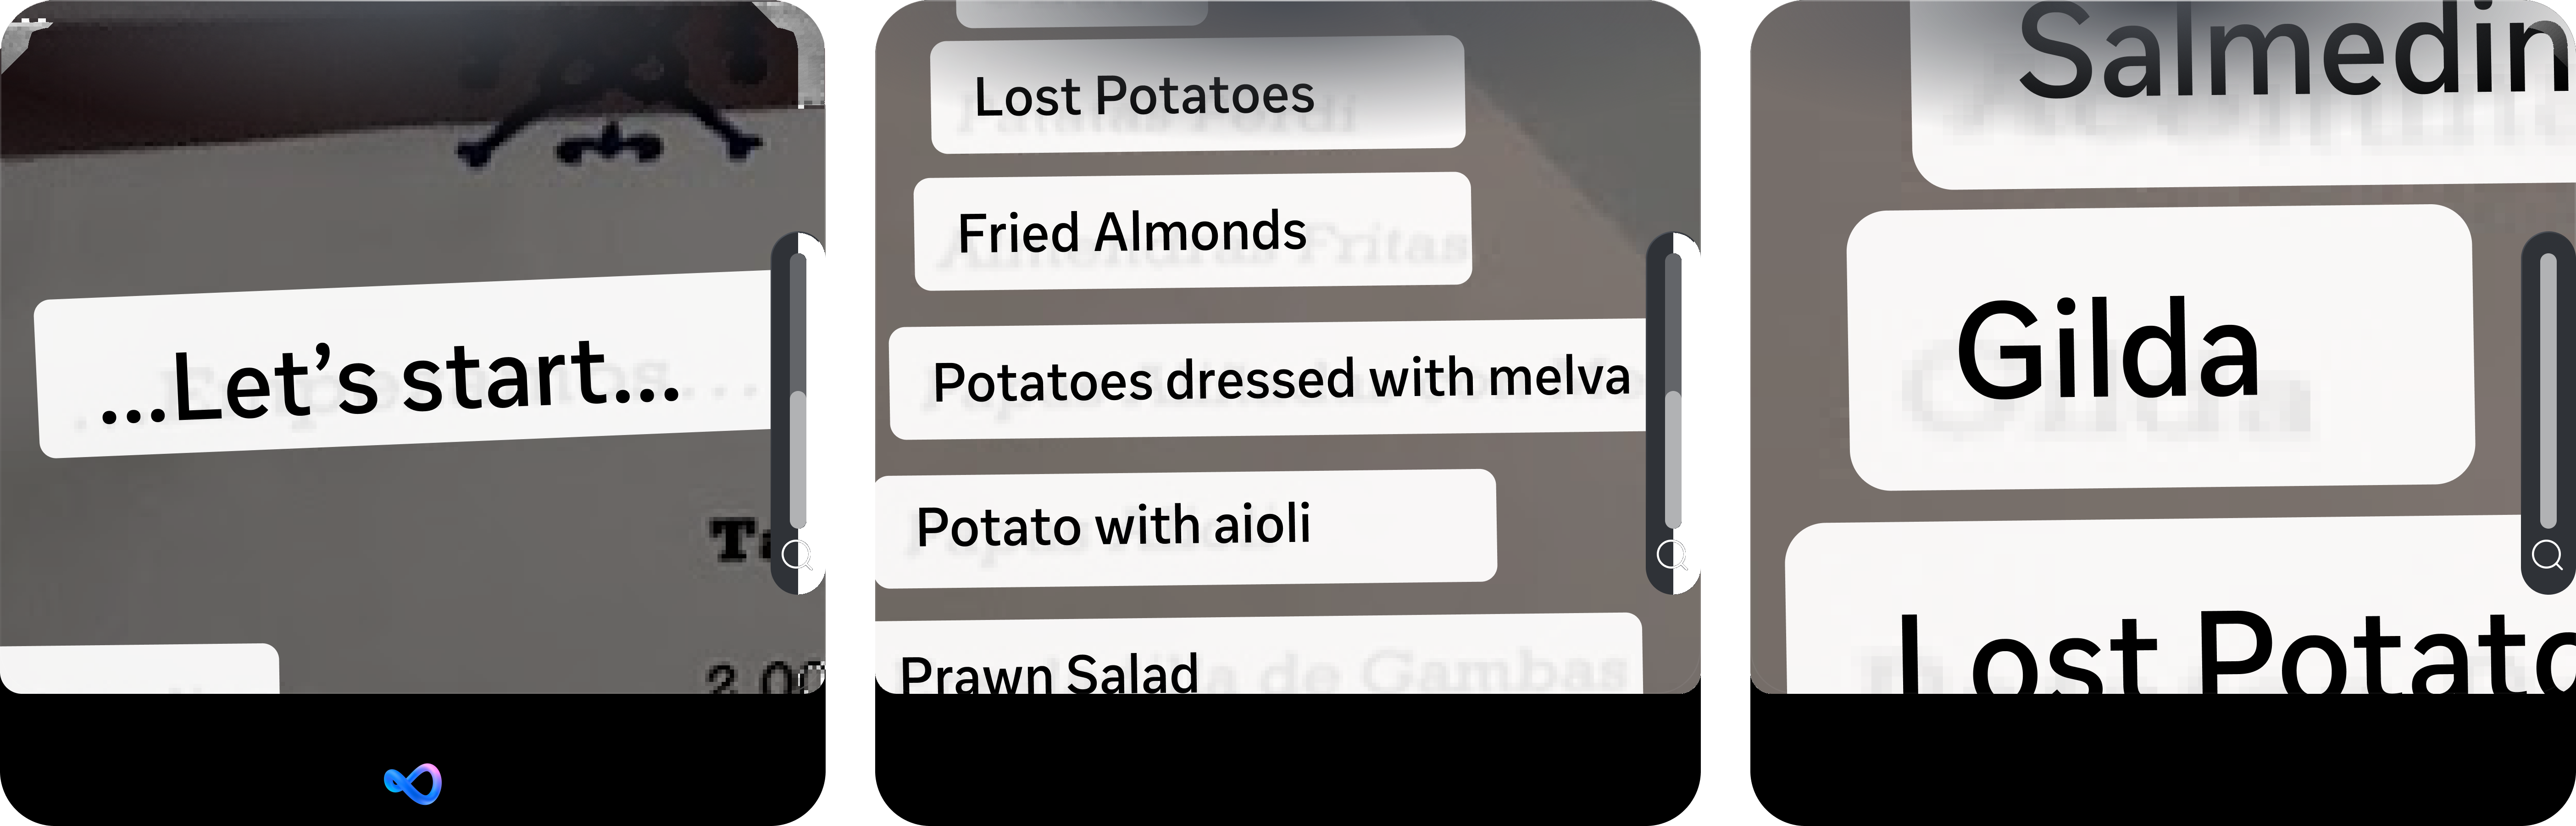
Next, how do you move through it — on a screen this small, with nothing to touch? Constant pinch-pan-zoom is exhausting, so I bet on removing the manual work with Smart text selection.
Text selection may sound simple. But in reality it's much messier than you can imagine. Real-world text has various orientation, linebreak, and layout. Jiaqian and I relentlessly refined the calculation so the system identifies orientation, proximity, and chooses the next text block aligned with human reading order. The calculation also reduces panning to the minimum to avoid dizziness.
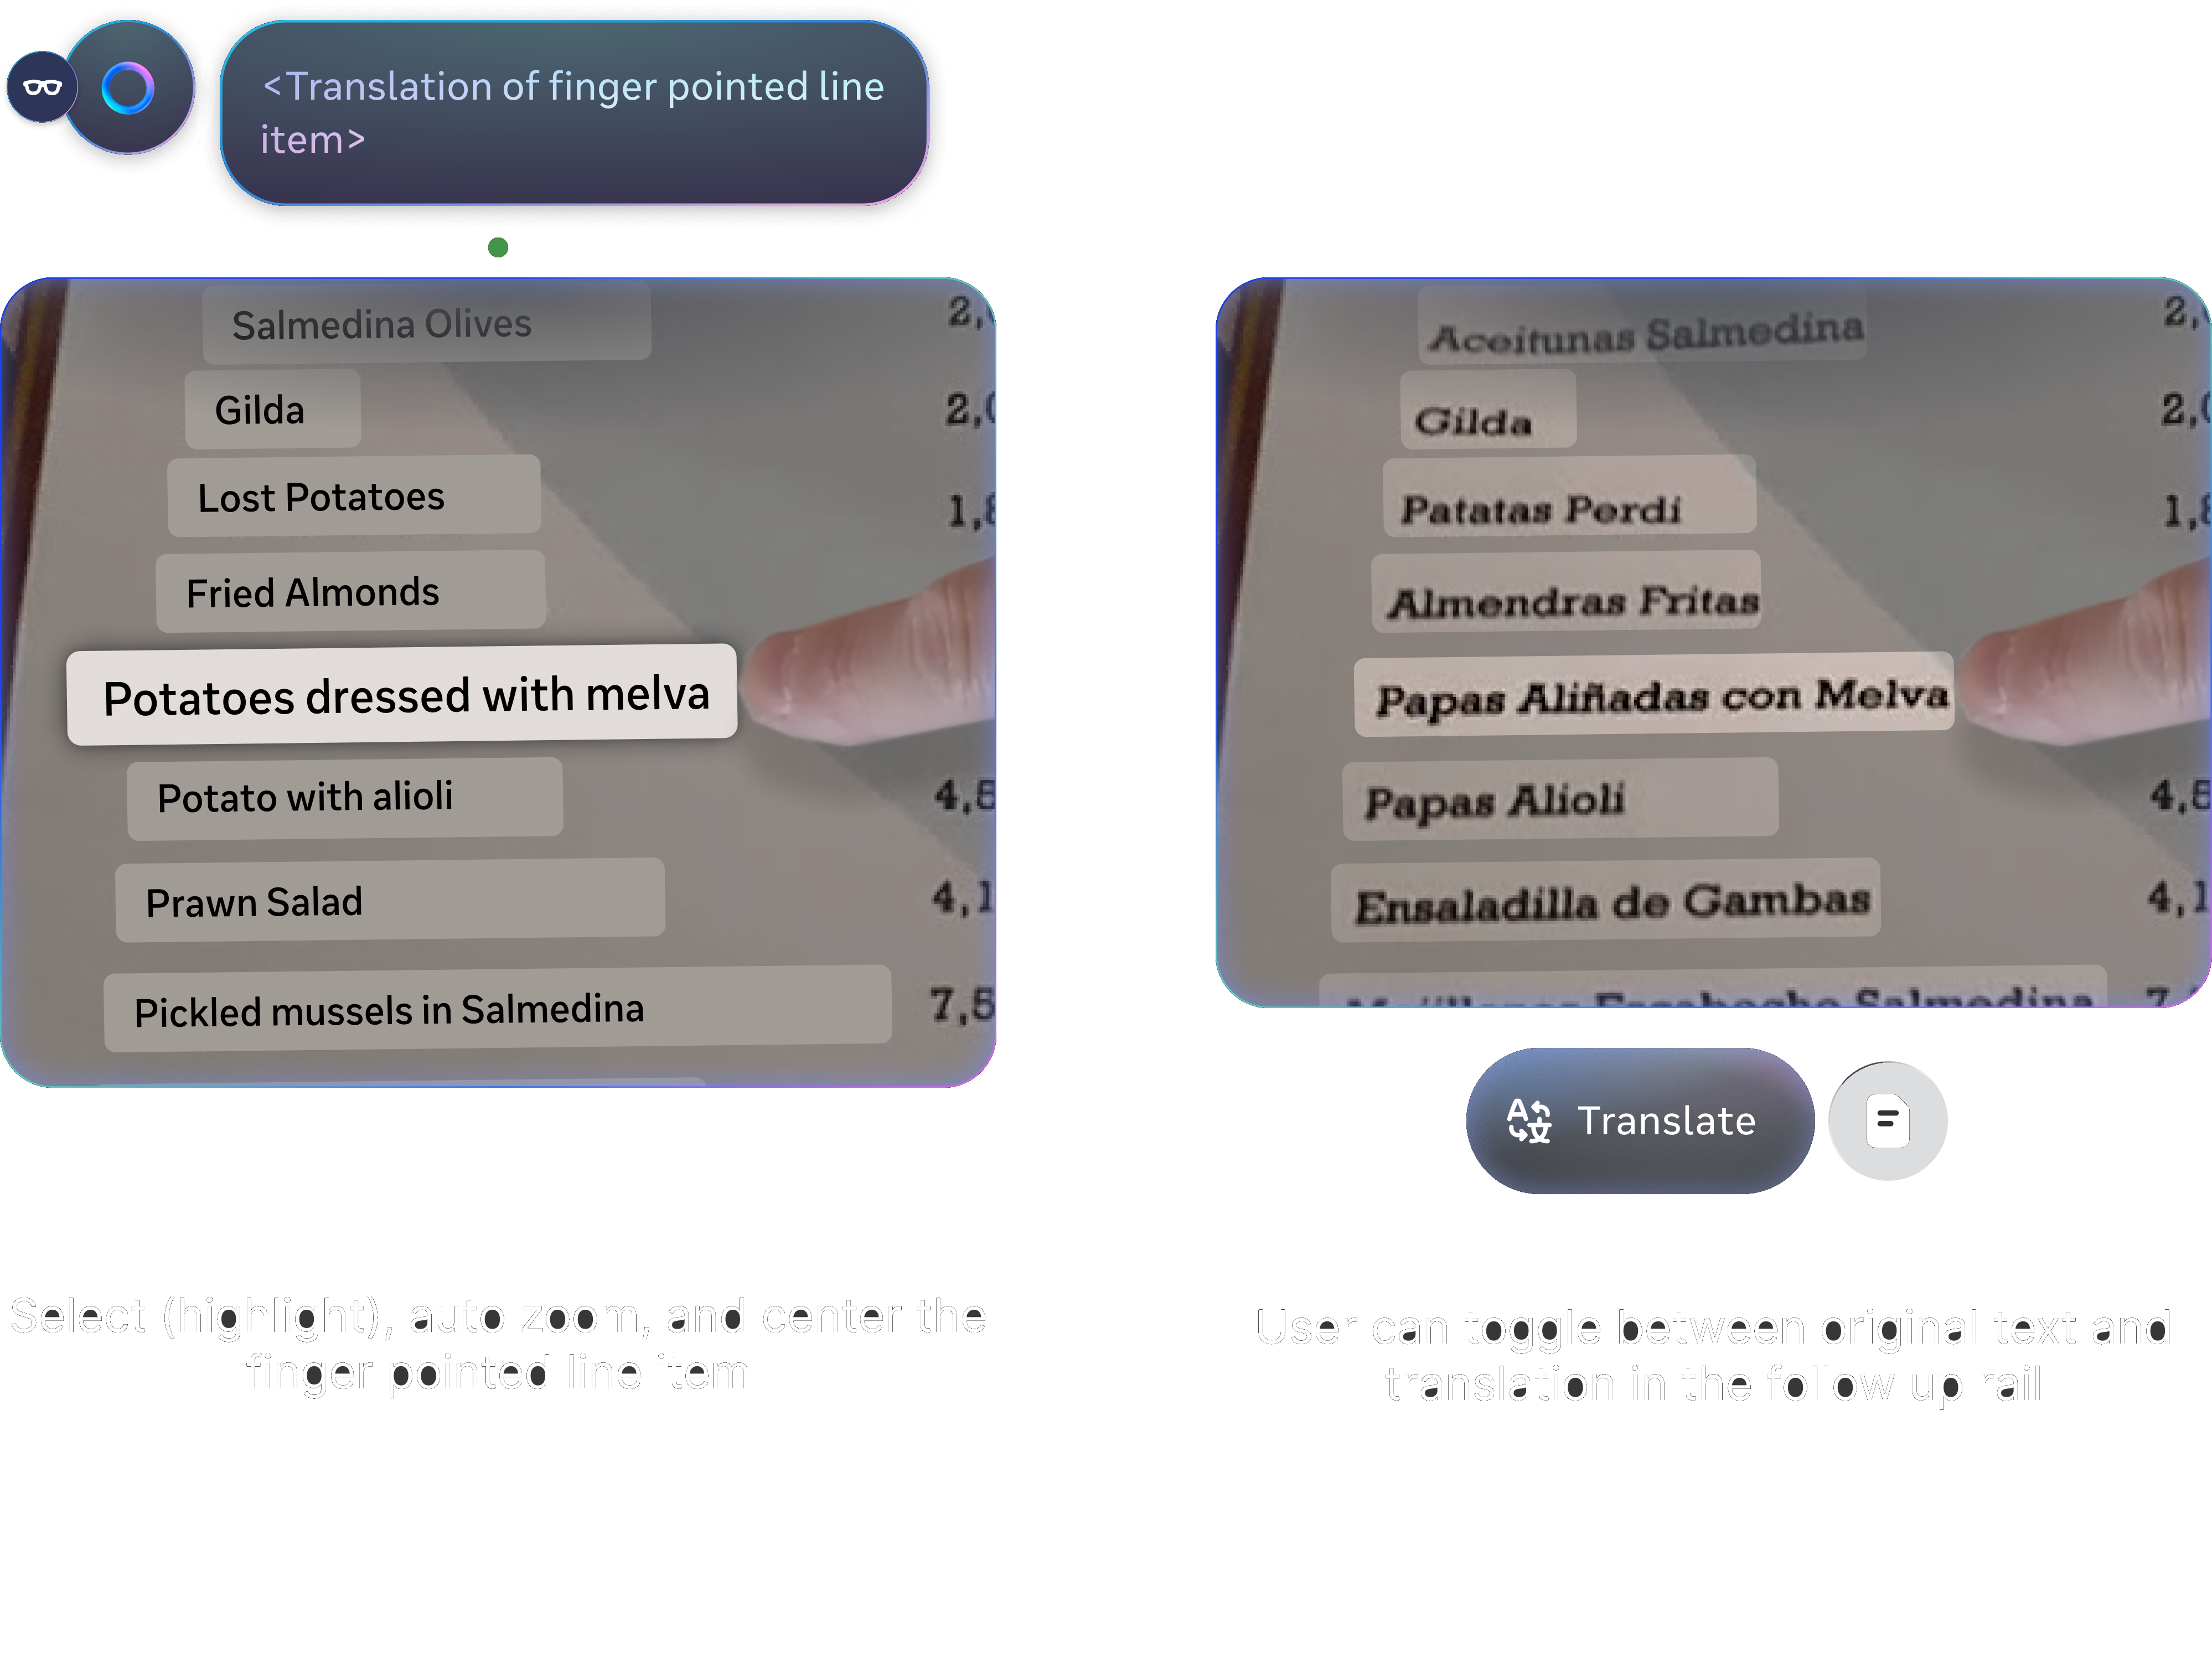
Two ways to get from one line to the next with nothing to touch.
Both auto-zoom; they disagree about what moves — the image, or the selection.
- Potentially less dizzy as the capture pans less during selecting state
- Hard to distinguish between the detected highlight and the targeted highlight
- Different mental model from most of the image panning mechanism and different from how panning in other experiences works on HN (moving viewport + fixed image)
Flexibility was the design —
not the fallback.
Not everyone agreed on leaning this hard on automation. Leadership pushed to keep manual free pan-and-zoom. We didn't settle it by winning; we made the modes complement each other: smart selection for the common path, free pan-and-zoom whenever you want it.
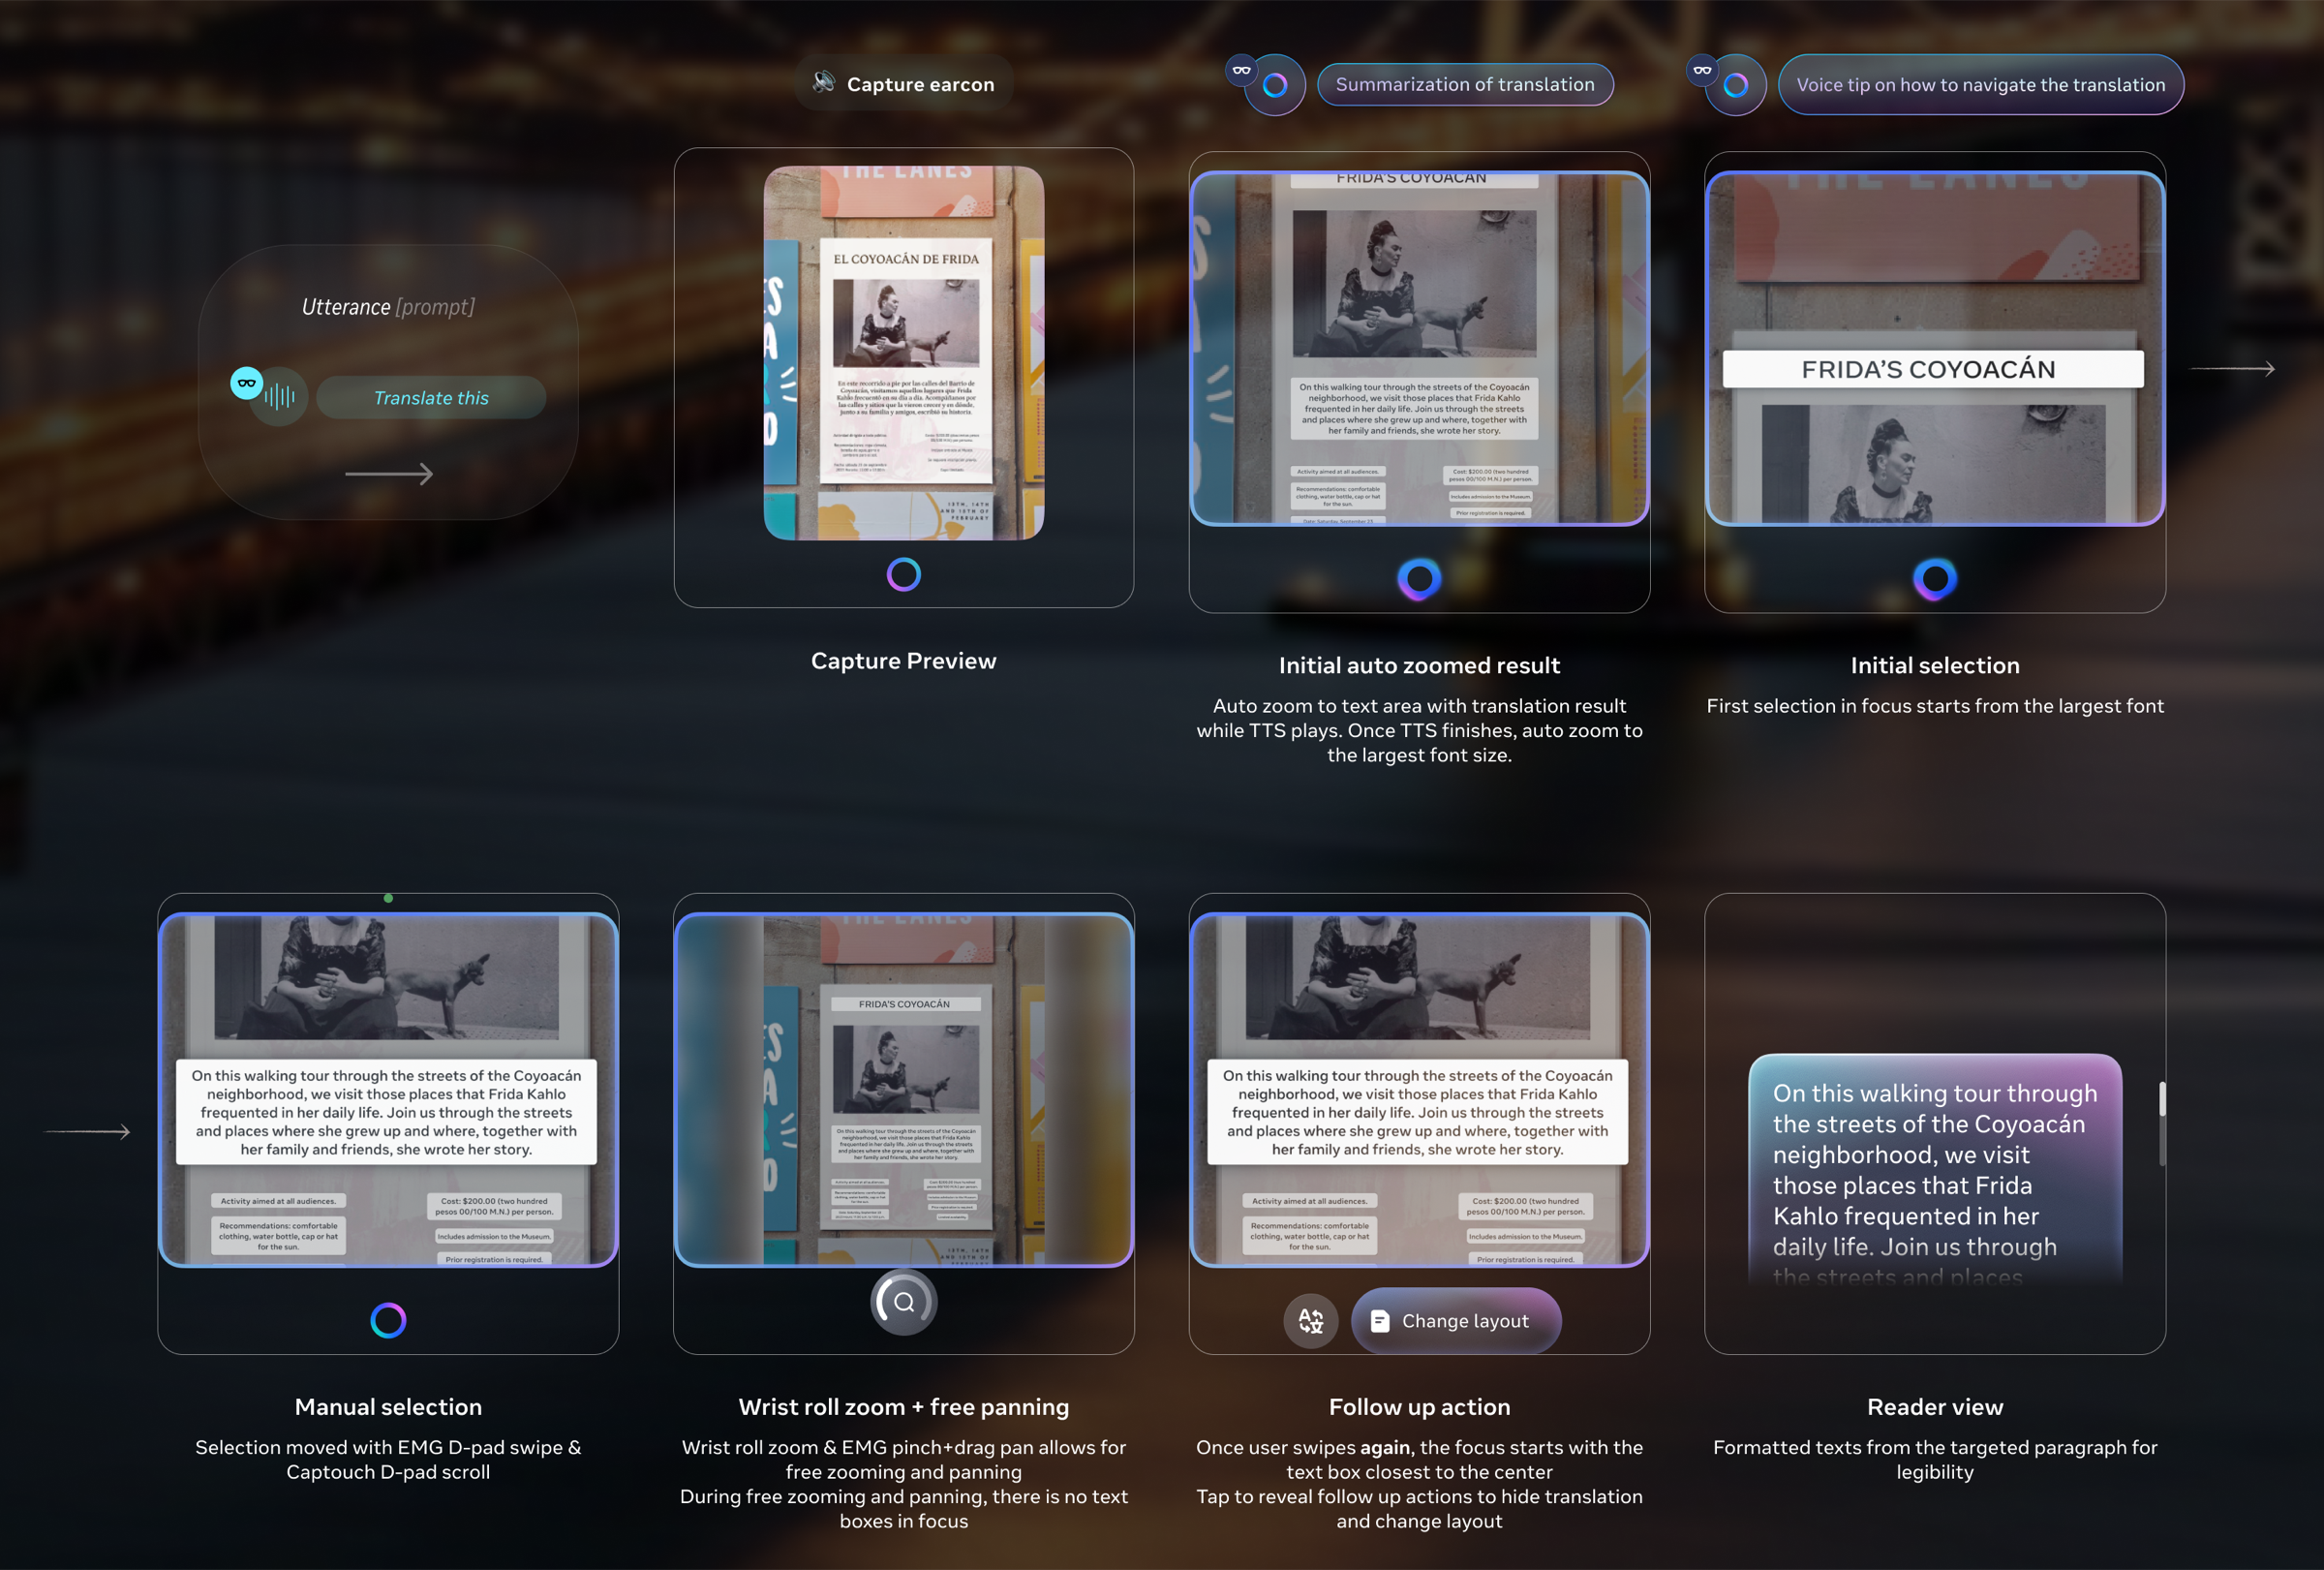
How it works.
Ask generically by natural invocation or specify with your finger.
Pinch and drag to pan where you want. Wrist roll to zoom in on the section. Swipe to consume each line.
Reveal the original language or shift long-form text into system template tuned for 600 × 600 legibility. Other follow up actions are designed and scoped in future milestones.
Resolve gesture conflict, provide contextual education
3x the recall rate, 3K DAU on launch
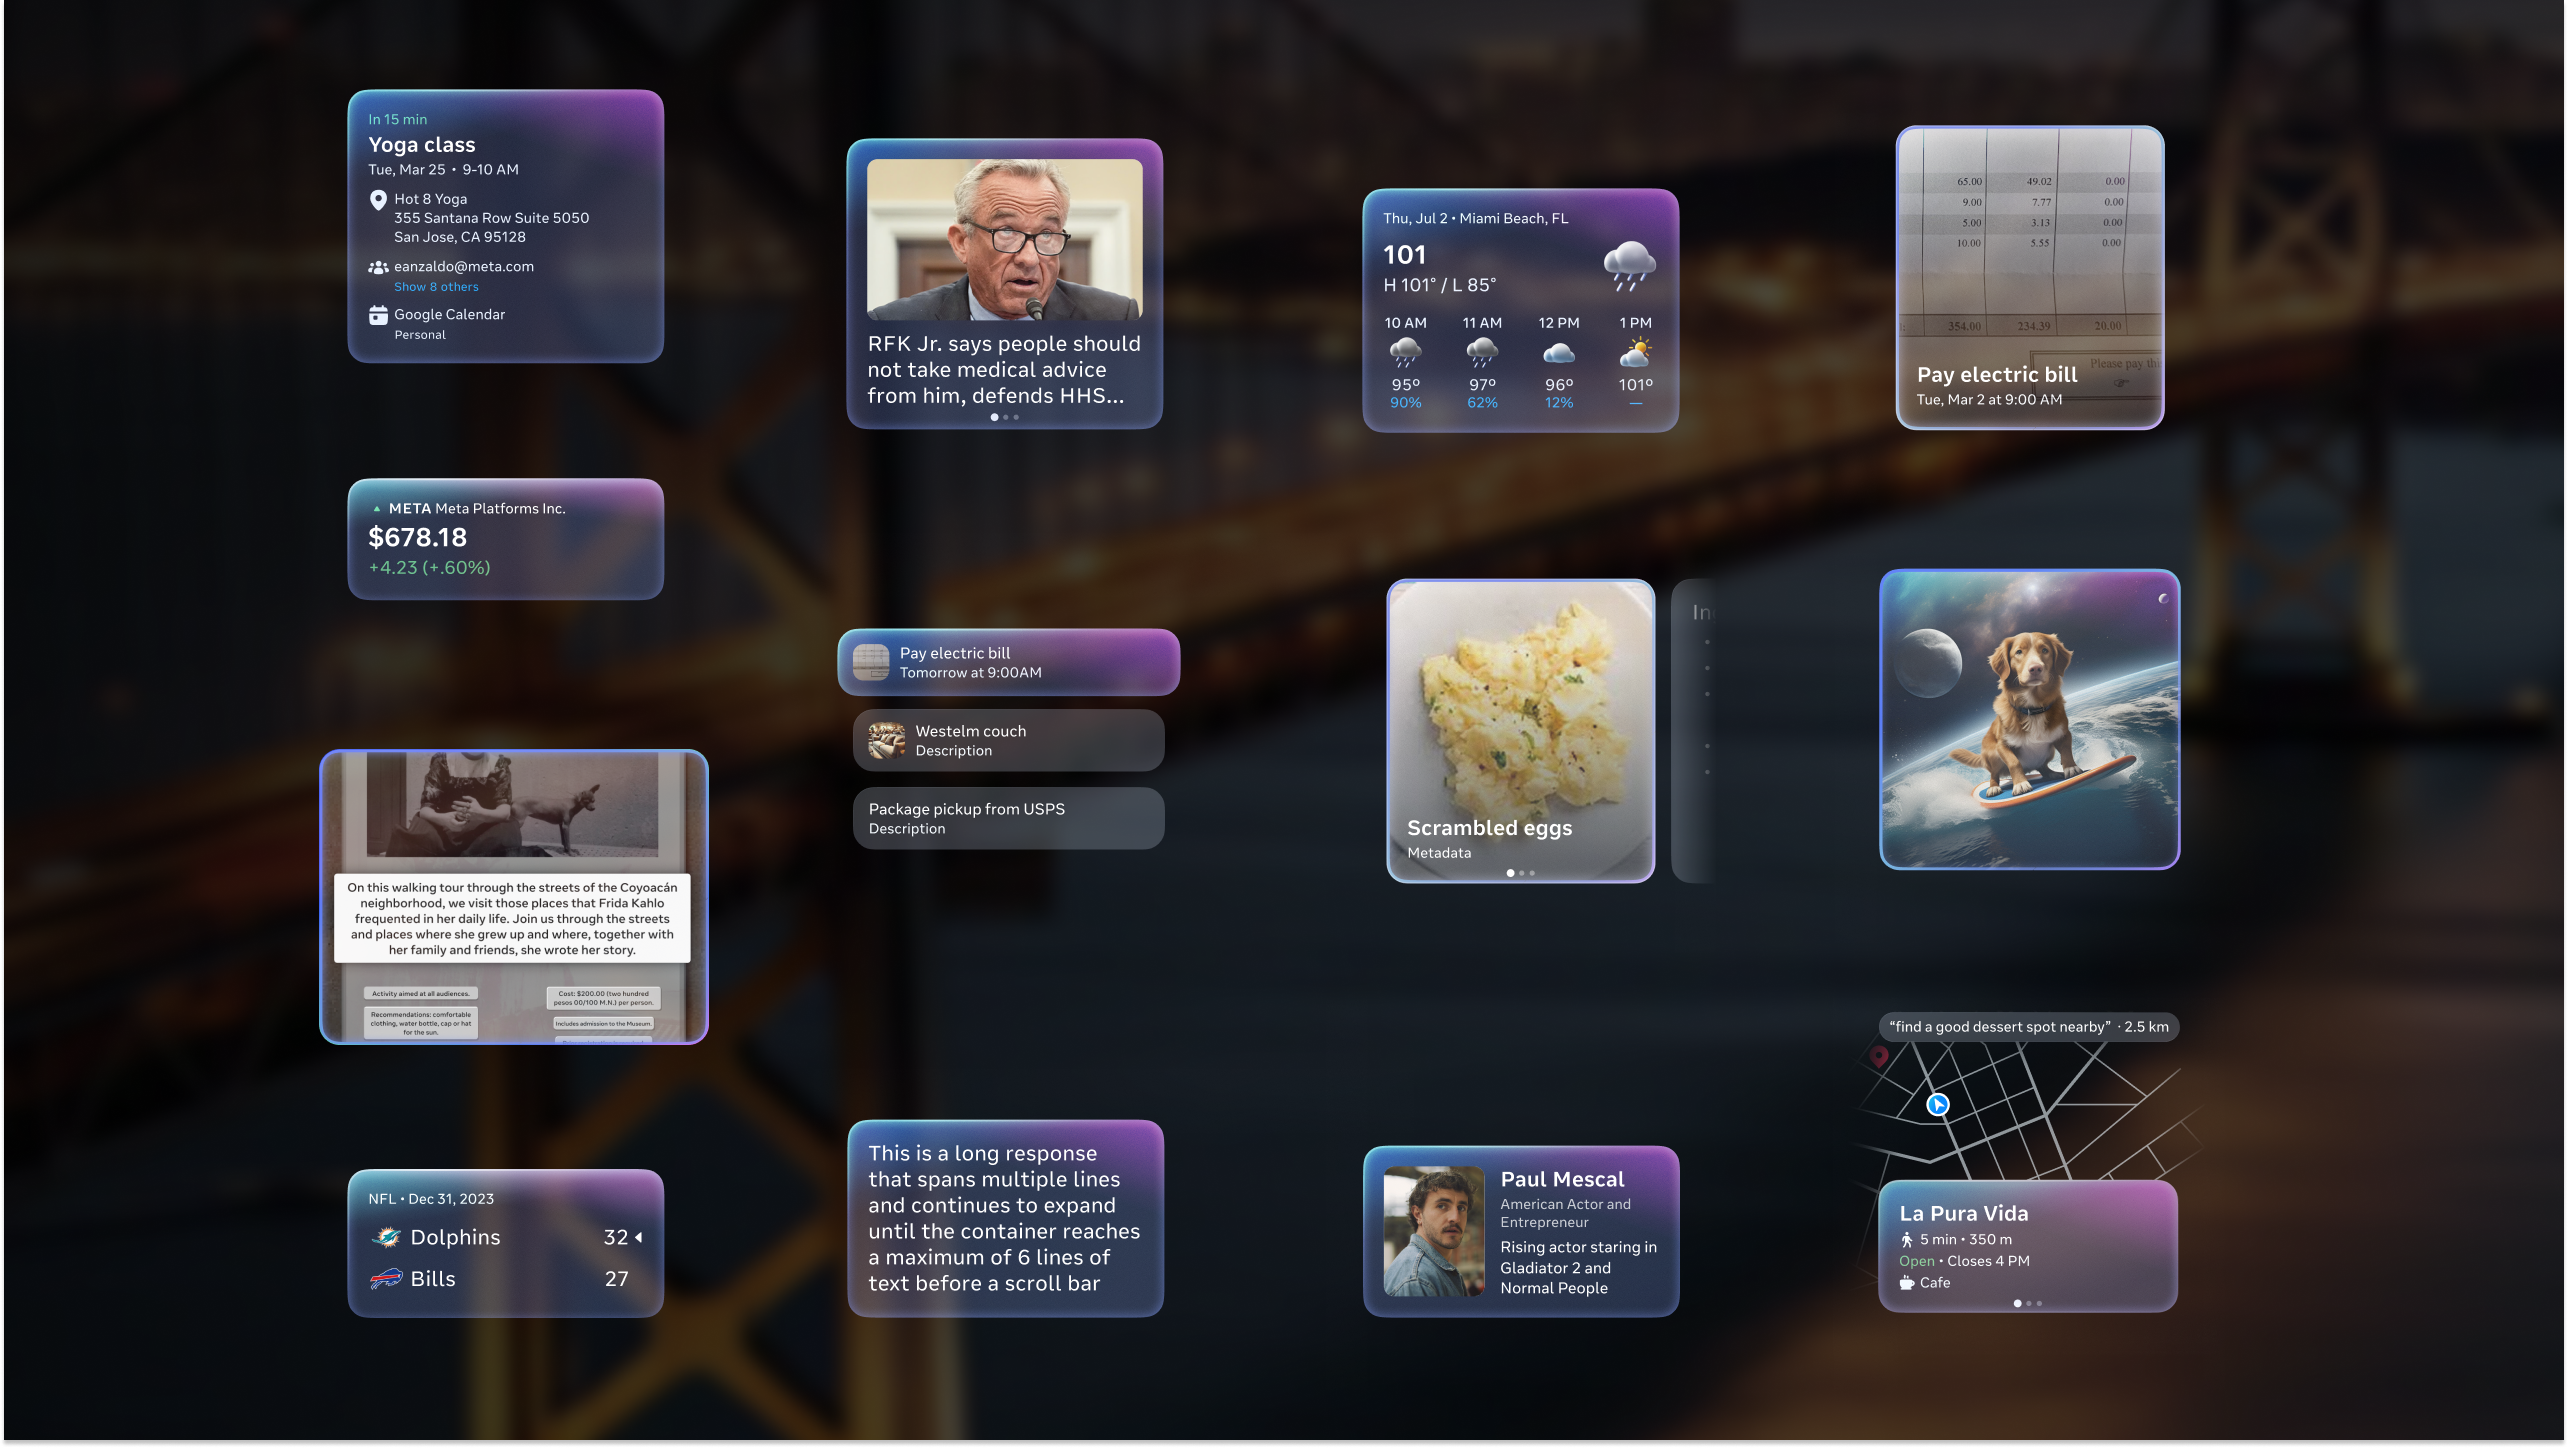
The pixels were never the whole story.
Accessibility doesn’t translate from one to the other
What’s clearly distinguishable on a touchscreen doesn’t translate to a transparent display. I ensured all designs were tested on the glasses, in the conditions people actually wear them.
Understanding the backend surfaced the problems earlier
Once I understood how the backend worked technically, I could see the quality issues before the build did. It supercharged my iterations and pushed me toward a holistic solution.
Audio is the more precious real estate
You can glance past whatever is on a display, you can’t skip audio. We needed display and audio logic framework for this new form factor so that the two complement each other as one solution effectively.